Perch AI Research

Research from real traffic.

We serve open models on our own GPUs with real agent work, as research. We publish what that teaches us about models, hardware and serving: what we measured, on what, and what we changed because of it.

Latest study

Model
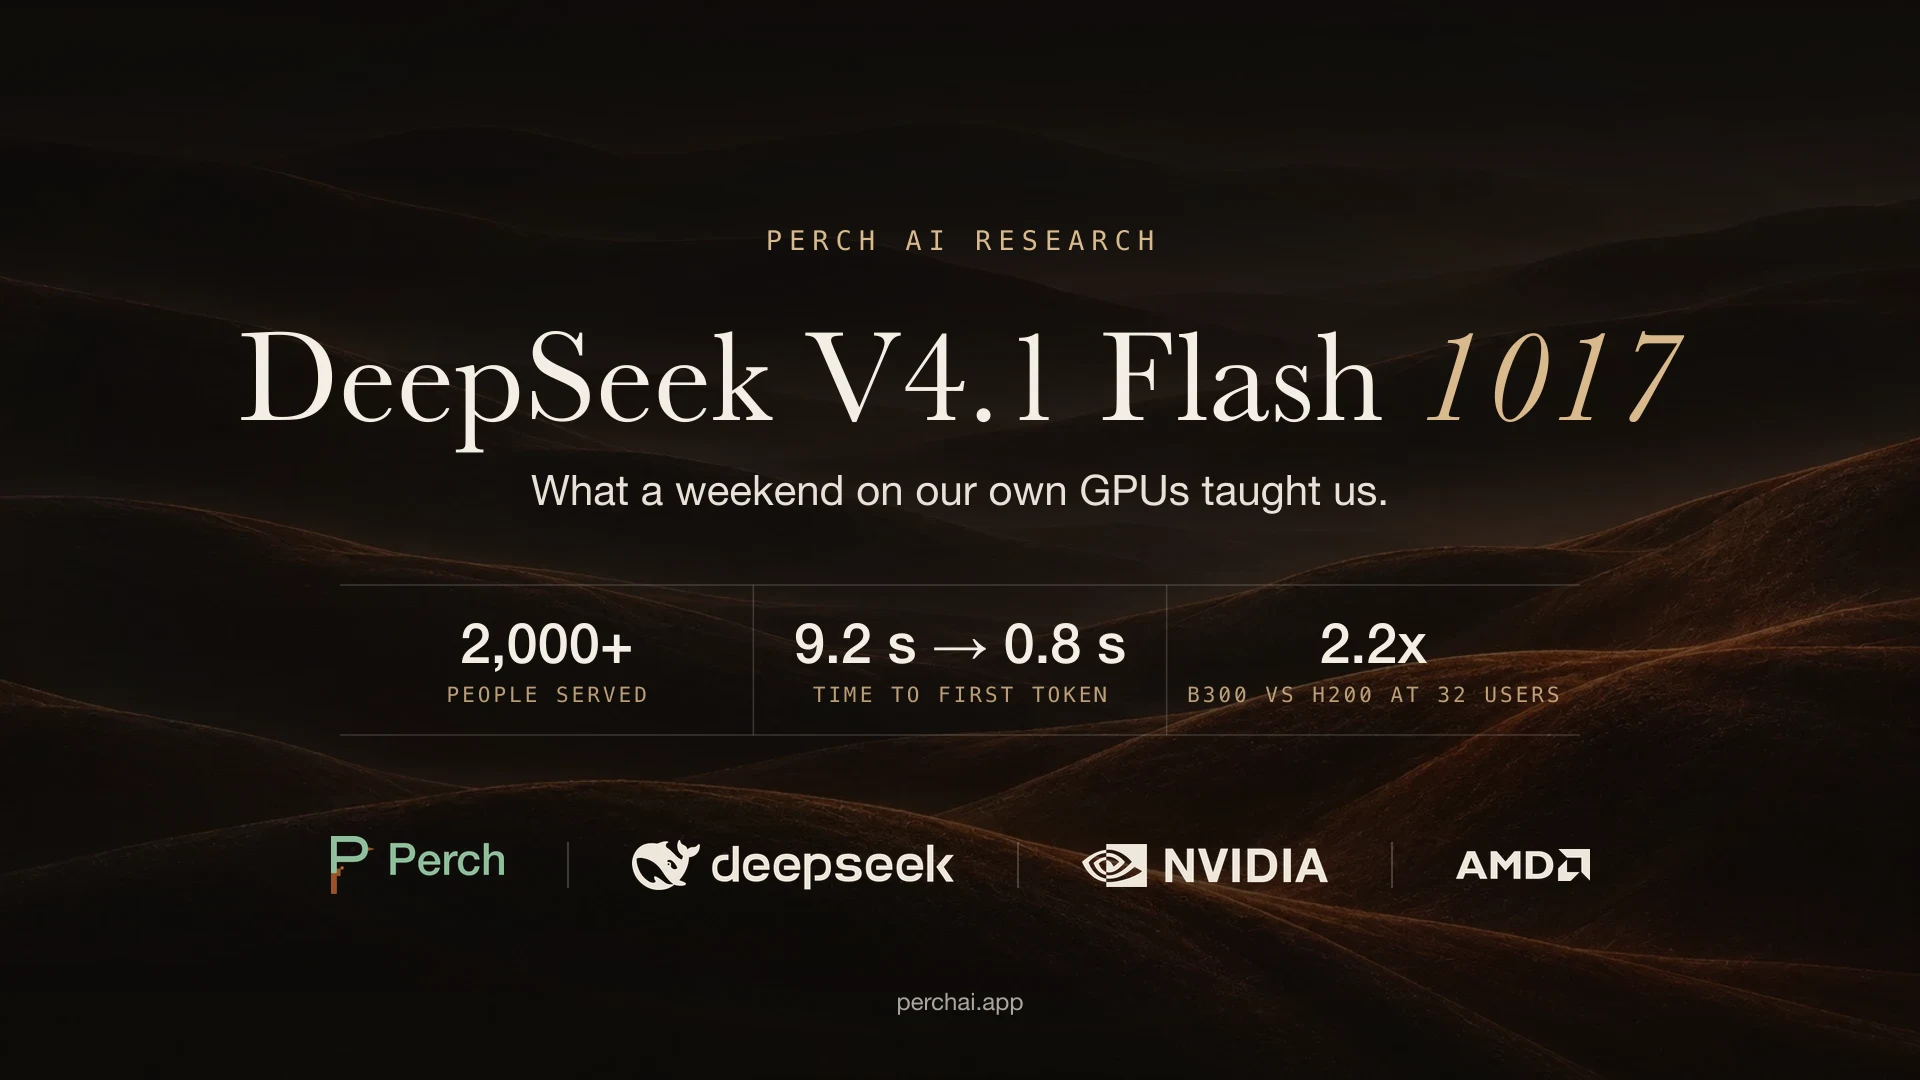
DeepSeek V4.1 Flash 1017
Hardware
B300, MI355X, H200
Engine
vLLM
Weights
Official, unmodified
How we served it

From the study

With one user, MI355X was the fastest of the three. As soon as several people shared a node, B300 pulled ahead and stayed there.
  • NVIDIA B300
  • AMD MI355X
  • NVIDIA H200
Self-hosting DeepSeek V4.1 Flash 1017: what a weekend on our own GPUs taught us, Nov 9, 2026

What we learned

  1. Hardware with native 4-bit math won by a wide margin.
  2. The slowest part of the stack was a CPU process, not a GPU.
  3. The looping people reported is the model itself, so we built a guard for it.

All research

Partner with us

Run GPUs or serve models? Run the next study with us.

Real agent traffic, published numbers, your name on the report.

Talk to us