Vision in AI agents: why the model that sees should not be the model that decides
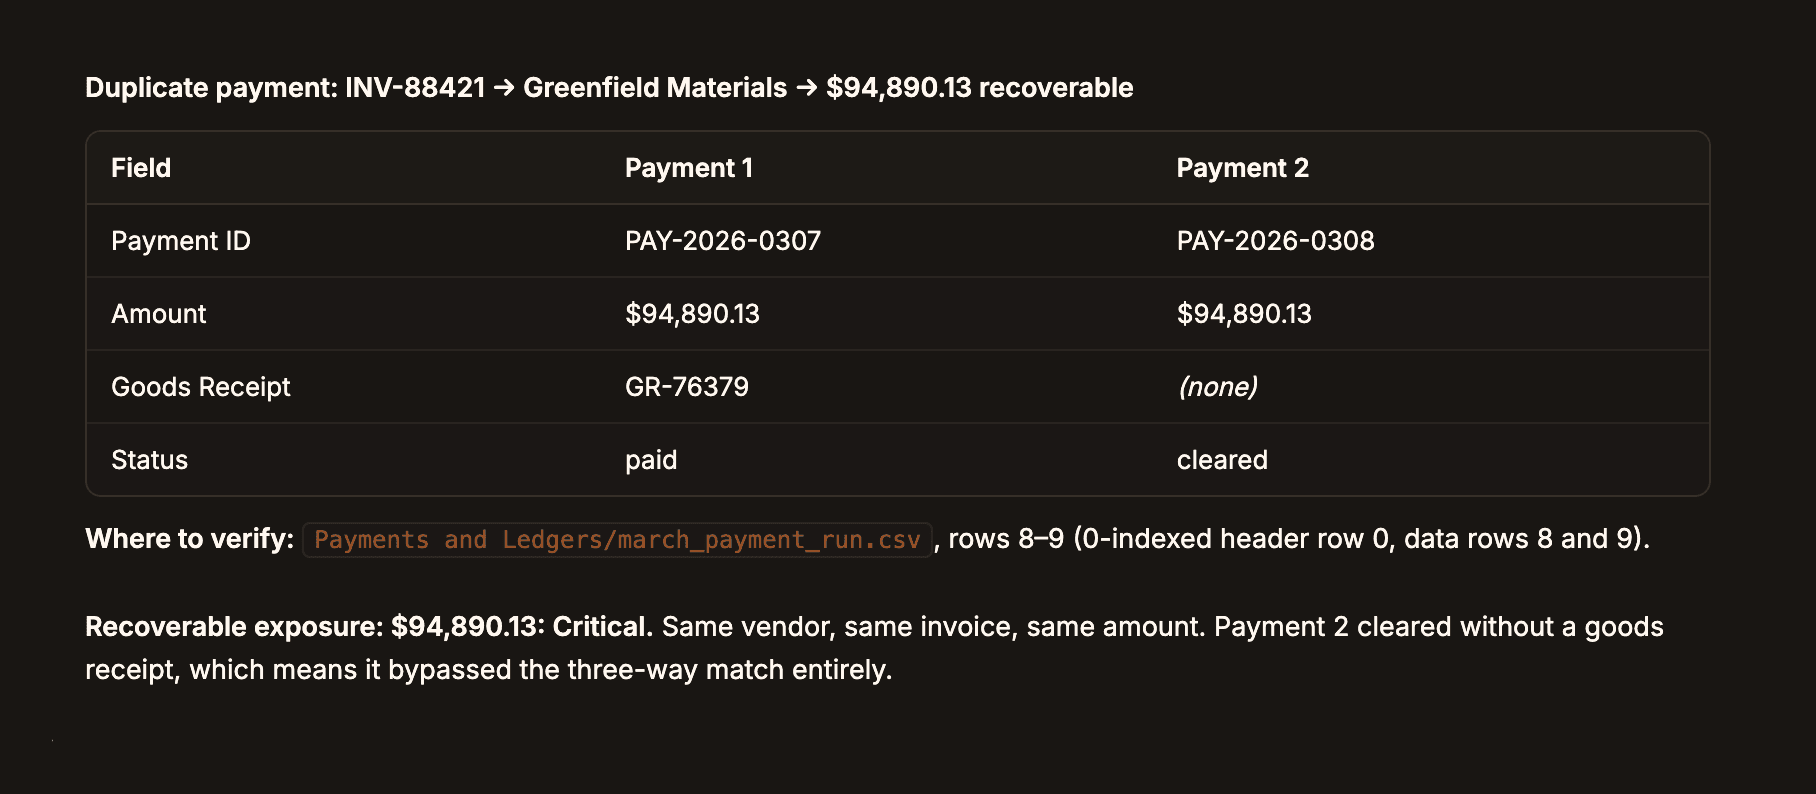
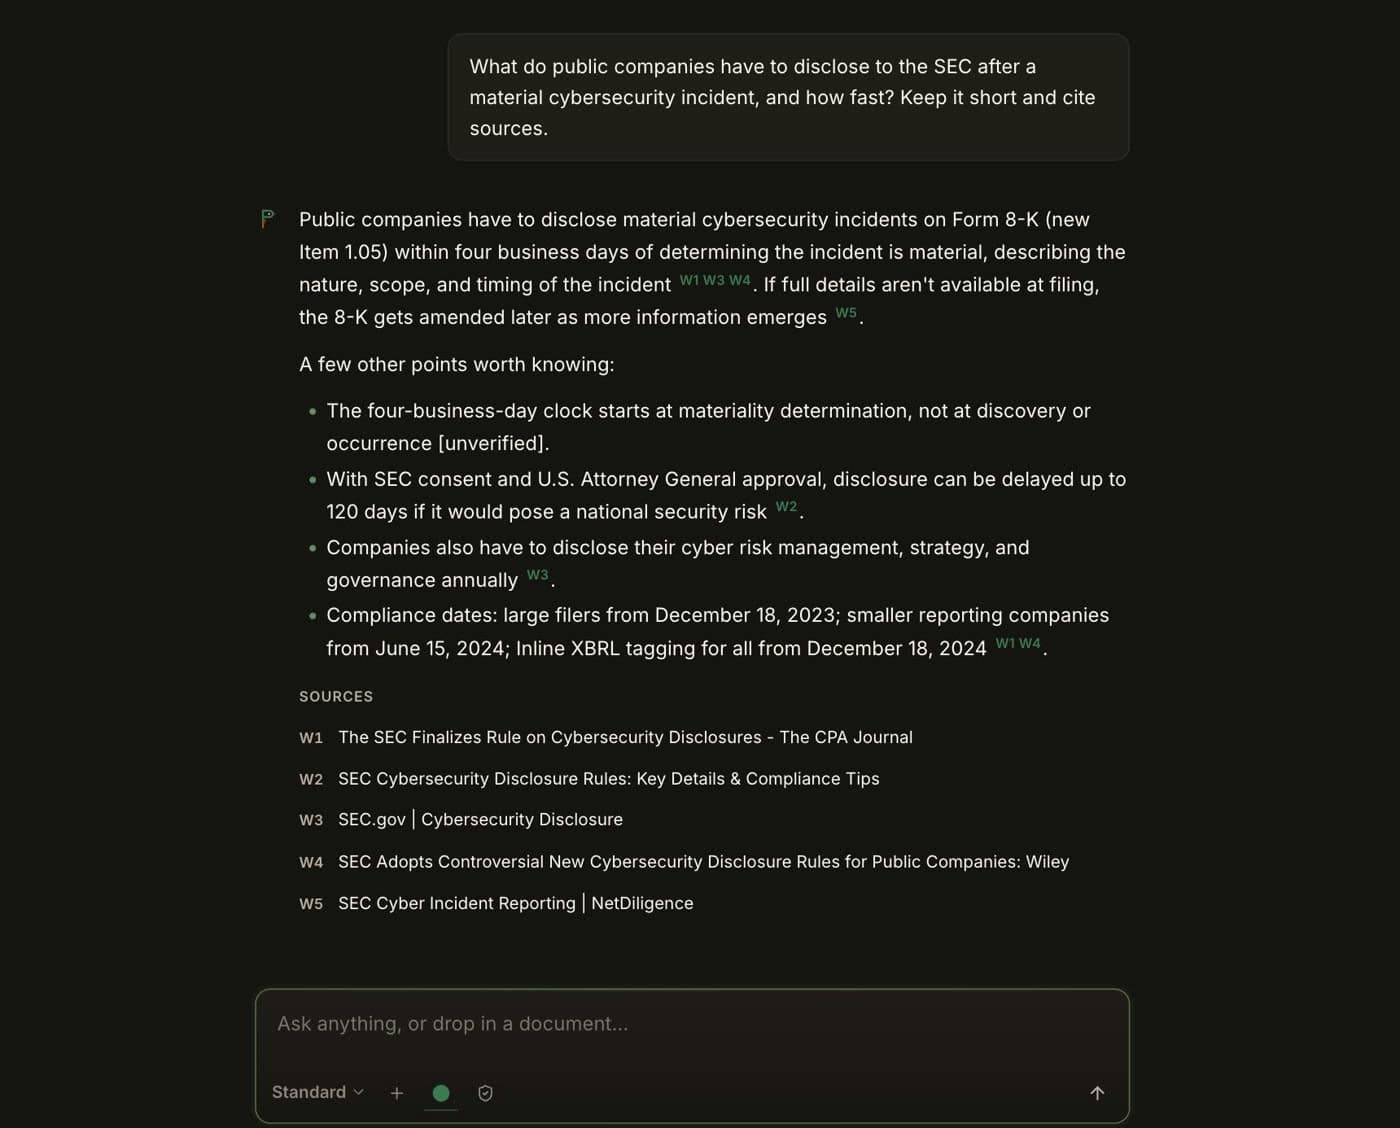
The strongest reasoning models are text-only. The standard fix is to swap in a multimodal model, which silently downgrades every turn of your agent, including the ones with no image in them. There is a better shape, and it has rules.
5 ส.ค. 2569 · 9 min read