Announcements

What’s new at Perch

Product updates, launches, and changes, newest first.

November 19, 2026

2x DeepSeek on Pro and Ultra, through December
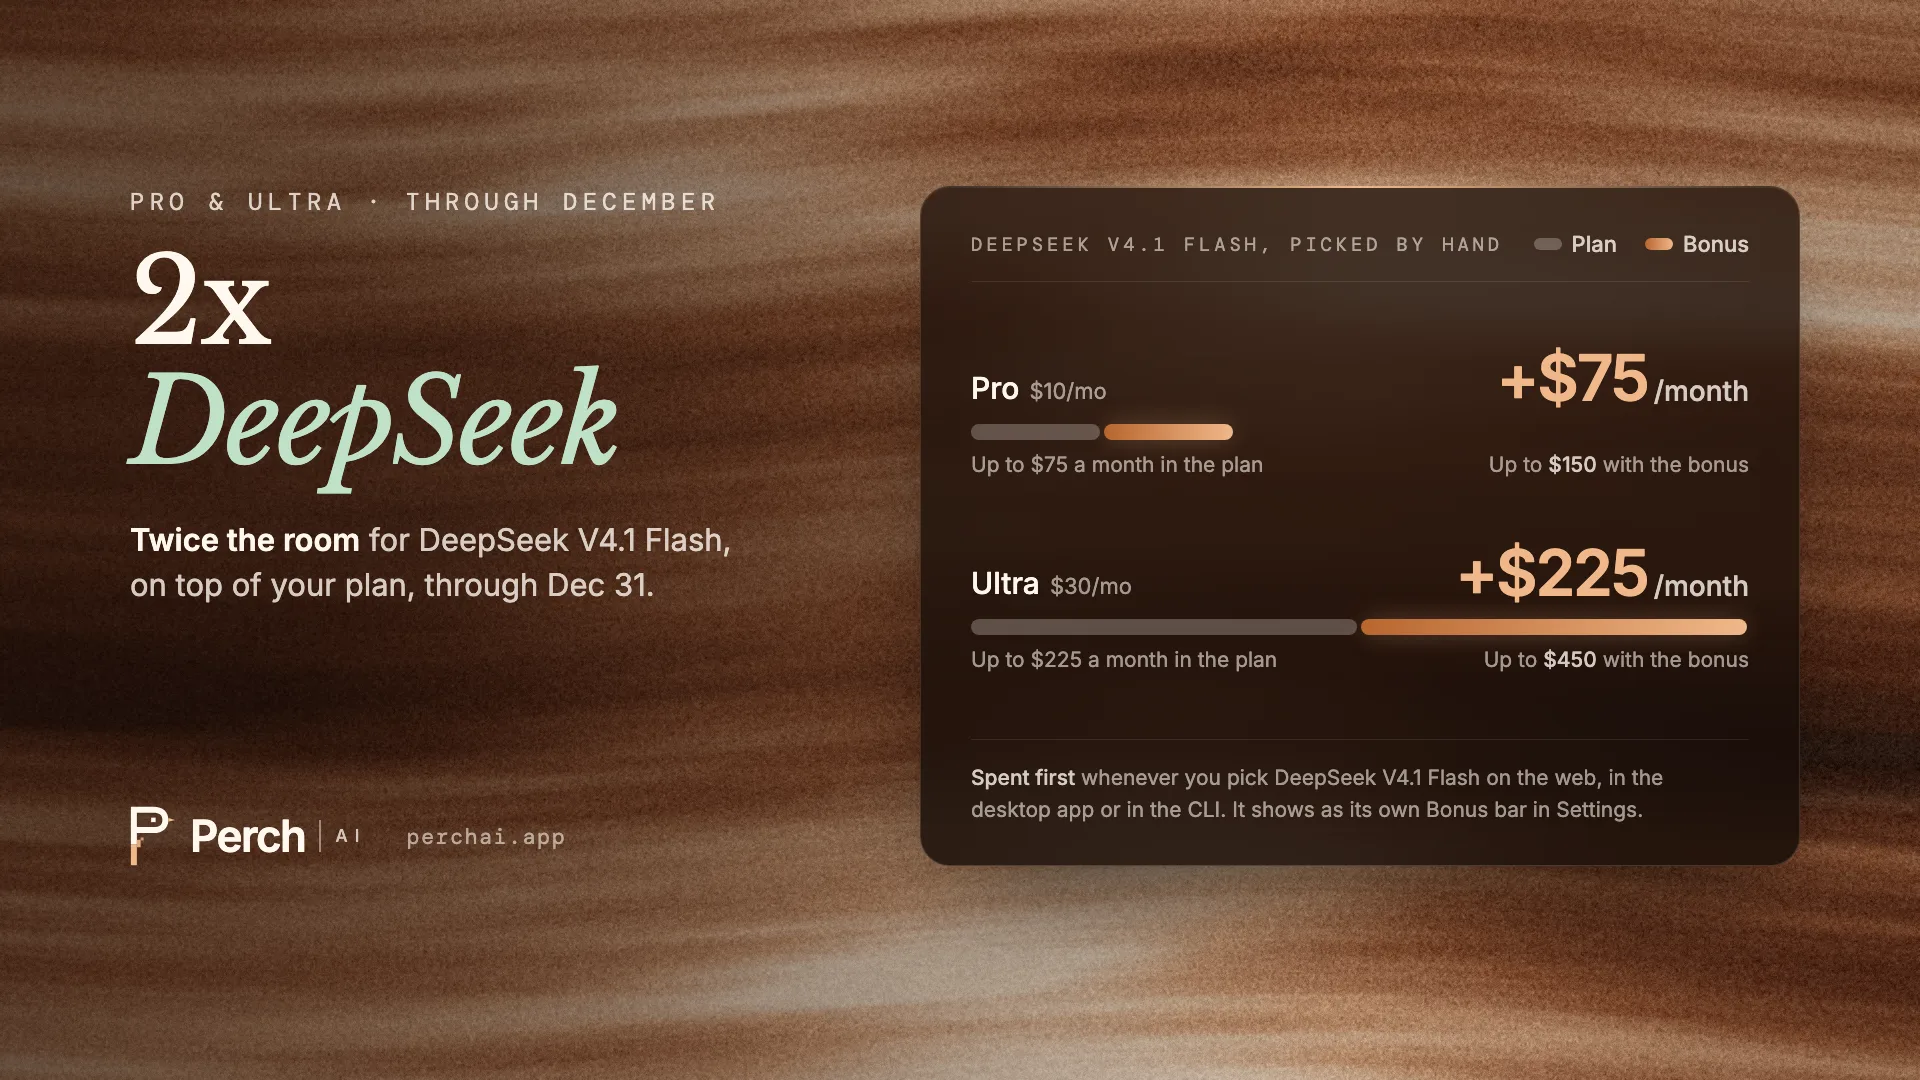
2x DeepSeek: Pro gets an extra $75 a month and Ultra an extra $225 a month for DeepSeek V4.1 Flash picked by hand, on top of the plan, through December 31. Up to $150 a month for DeepSeek on Pro and up to $450 on Ultra.

Pro and Ultra now get twice the room for DeepSeek V4.1 Flash. On top of your plan, Pro gets an extra $75 a month and Ultra an extra $225 a month, used only when you pick DeepSeek V4.1 Flash yourself.

That is the same amount each plan already includes for models you pick by hand: $75 a month on Pro and $225 on Ultra. So DeepSeek V4.1 Flash can now use up to $150 a month on Pro and up to $450 on Ultra.

The bonus is spent first whenever you pick DeepSeek V4.1 Flash: in Perch AI on the web at chat.perchai.app, in the Perch desktop app, or in the CLI with /model deepseek-v4.1-flash-1017. When it runs out, DeepSeek V4.1 Flash uses your plan's normal allowance, as before.

It runs through December. November's bonus goes up today, from $50 to $75 on Pro and from $150 to $225 on Ultra. If you already used part of it, the extra is added to what you have left: $25 more on Pro and $75 more on Ultra. A fresh bonus of the same size starts at 12:00 AM ET on December 1 and runs through December 31.

It shows as its own Bonus bar in Settings, with what is left and when it ends. The bar counts in Perch Tokens: 1,000 Perch Tokens = $1, so 75,000 on Pro and 225,000 on Ultra.
November 18, 2026

Gemini 4 Neon is on Perch AI Ultra, day one

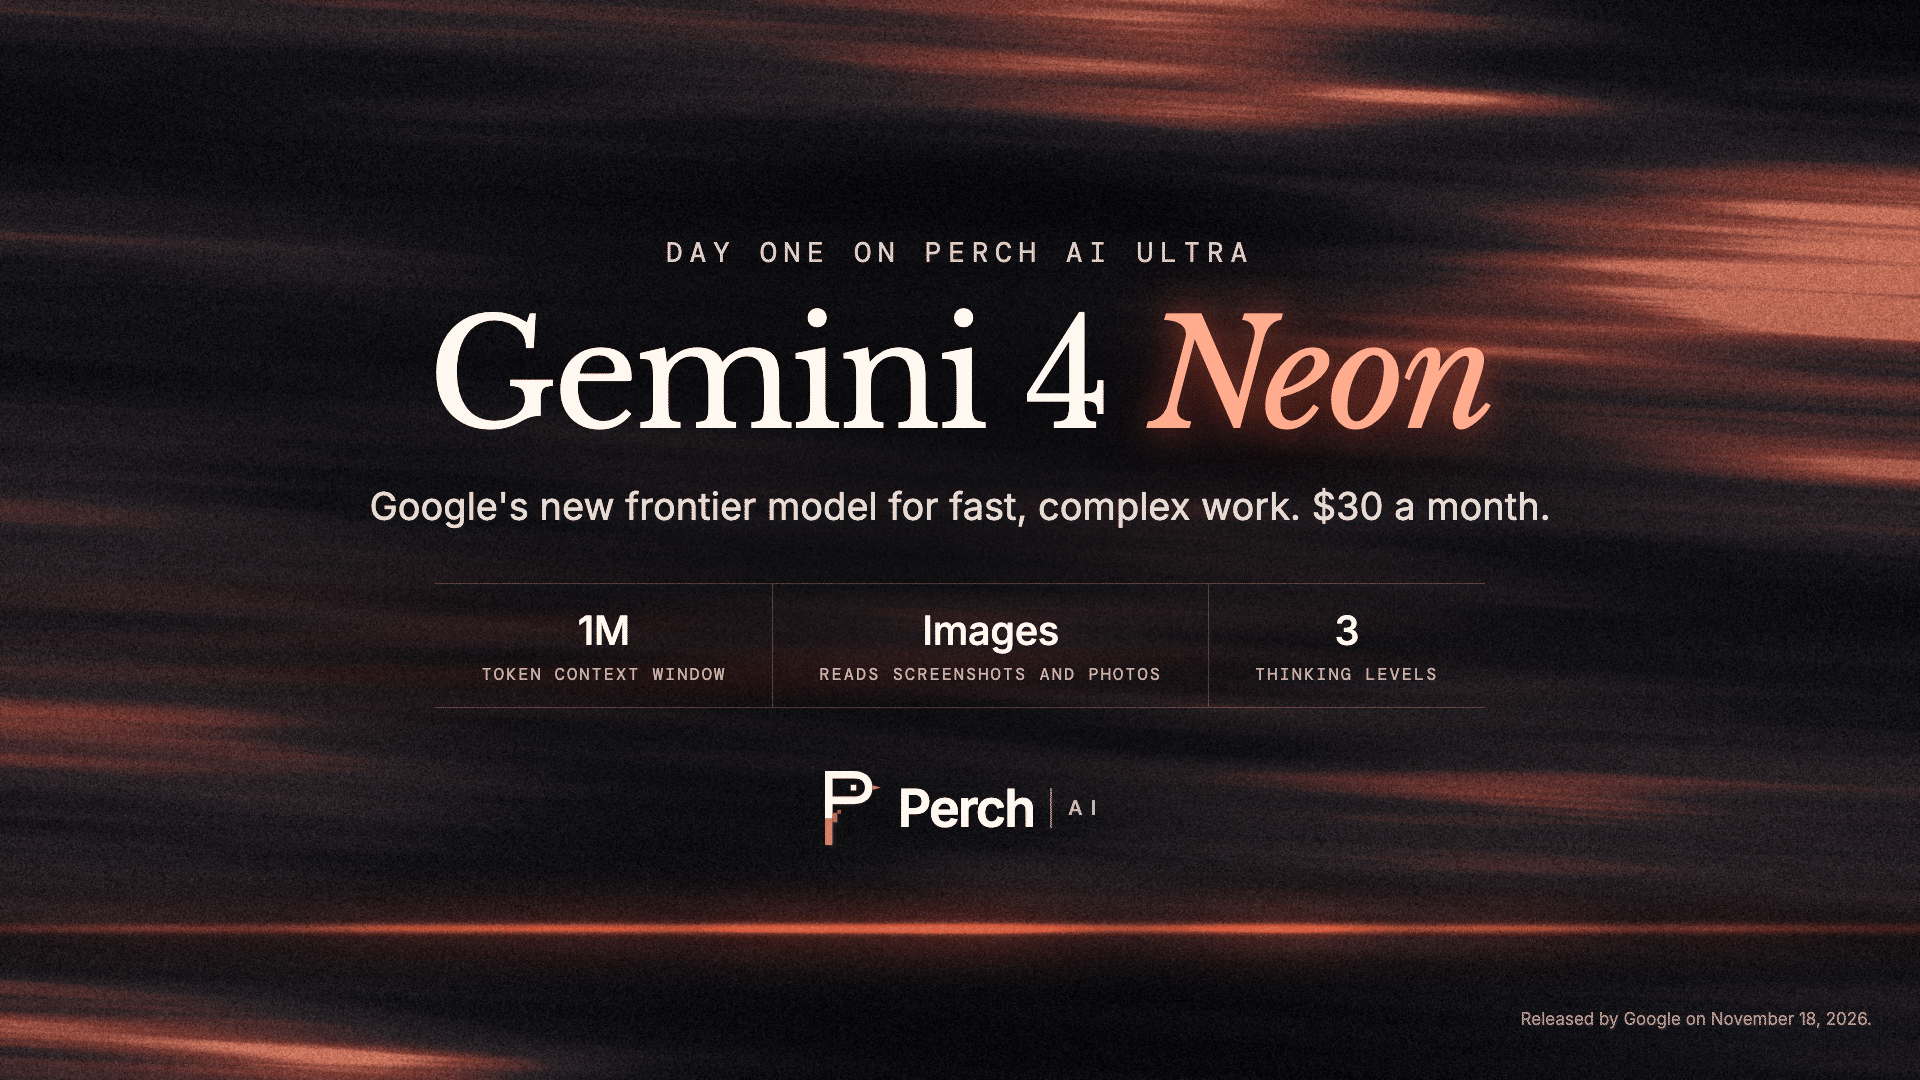
Gemini 4 Neon, day one on Perch AI Ultra: Google's new frontier model for fast, complex work, $30 a month. A 1M-token context window, reads screenshots and photos, three thinking levels.

Gemini 4 Neon, released by Google on November 18, is on Perch AI Ultra from day one. Ultra is $30 a month.

Neon is Google's new frontier model for fast, complex work. It reads images and has a 1M-token context window, with up to 64K output tokens. Its effort control runs low, medium and high. Google lists it at $3 input, $15 output and $0.15 cached input per million tokens.

It sits at the top of the models only Ultra can pick, ahead of Claude Fable 5.2 and GPT-6.2 Astra. Like them, it is pinned by hand only: Roost never picks it, and it draws from Ultra's manual allowance like every other pinned model.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model gemini-4-neon.

November 17, 2026

GPT-6.2 Astra and Sol are on Perch AI, day one

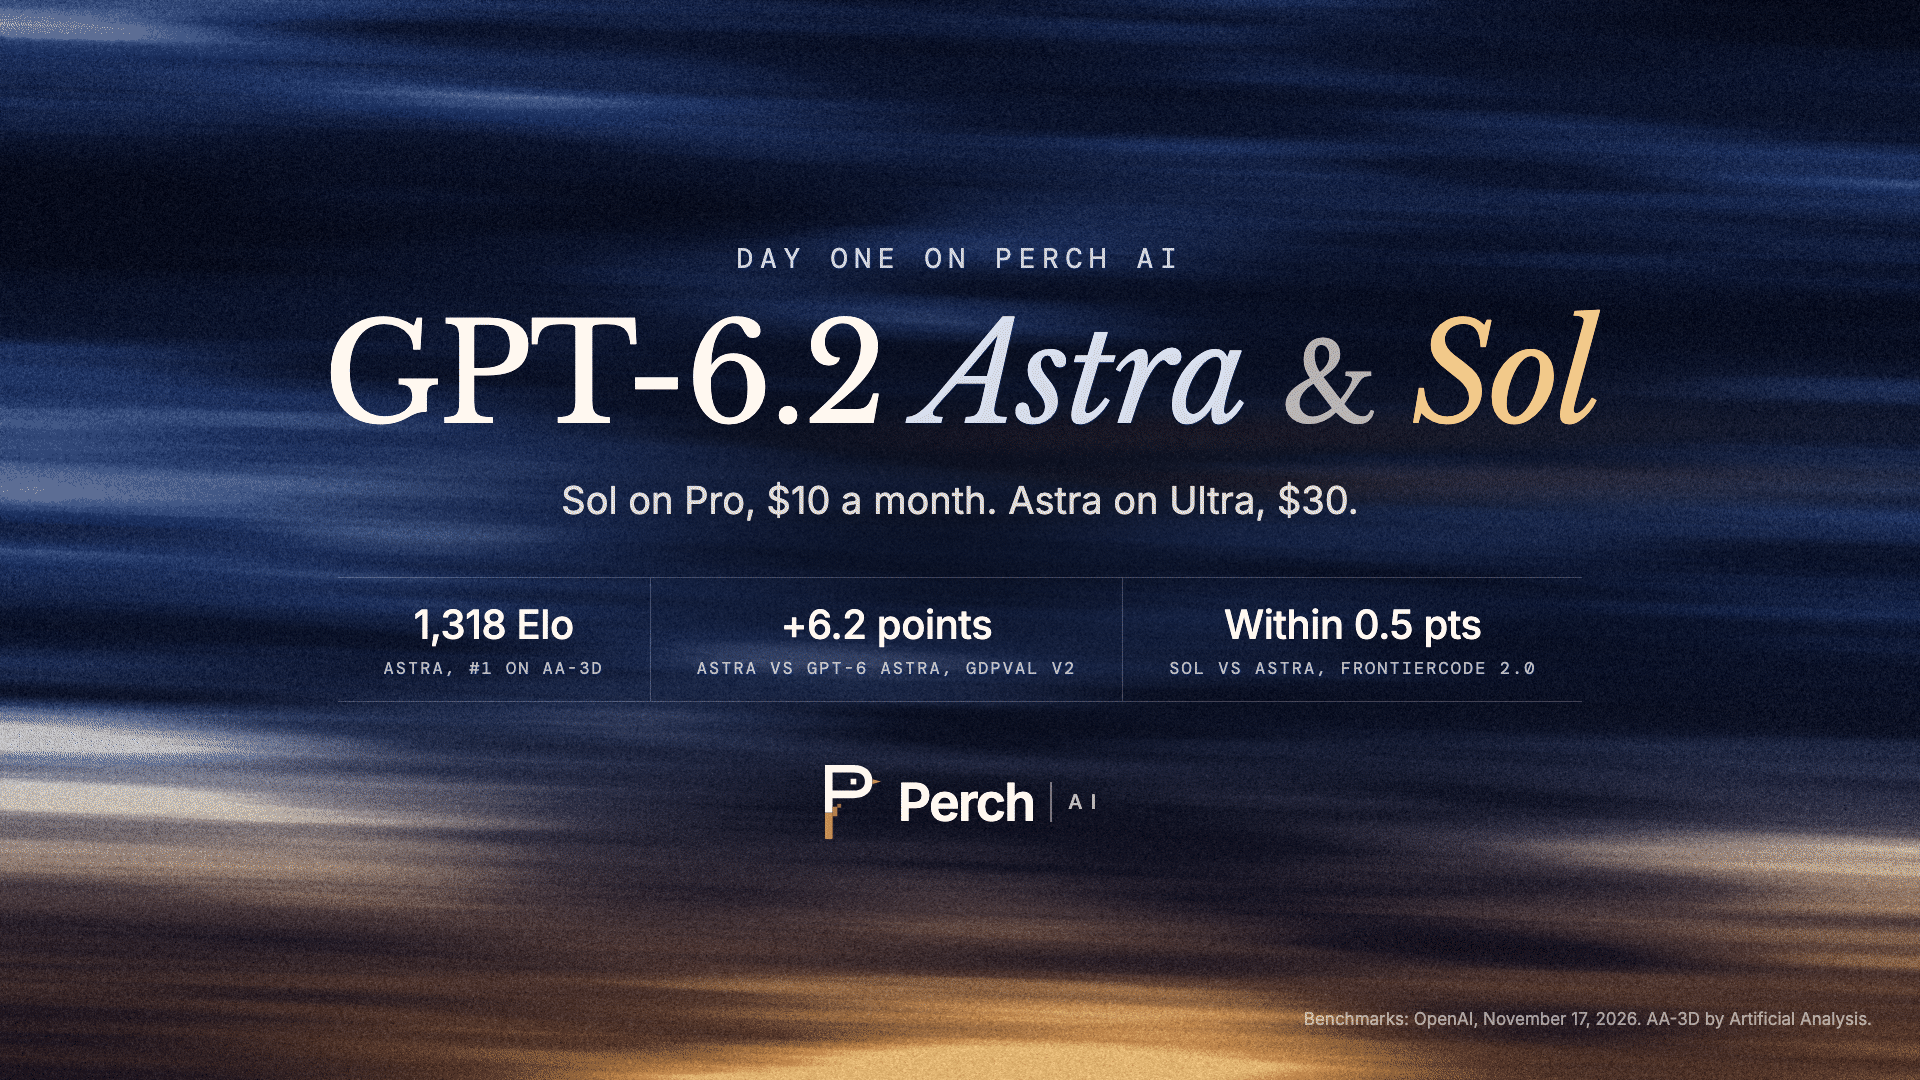
GPT-6.2 Astra and Sol, day one on Perch AI. Sol on Pro, $10 a month. Astra on Ultra, $30. Astra is first on AA-3D at 1,318 Elo and 6.2 points ahead of GPT-6 Astra on GDPval v2; Sol comes within 0.5 points of Astra on FrontierCode 2.0.

GPT-6.2 Astra and GPT-6.2 Sol, released today by OpenAI, are on Perch AI from day one. Sol is on Pro, $10 a month, and on Ultra. Astra is only on Ultra, $30 a month.

Astra is OpenAI's new frontier model for the hardest projects. In OpenAI's testing it ranks first on Artificial Analysis's AA-3D at 1,318 Elo, ahead of Claude Fable 5.2 at 1,271, and scores 6.2 points higher than GPT-6 Astra on GDPval v2 while writing 22% fewer output tokens. It also costs 20% less than GPT-6 Astra: $8 input, $40 output and $0.40 cached input per million tokens, so Ultra's included usage goes further.

Sol is OpenAI's model for everyday work. On Cognition's FrontierCode 2.0 it comes within 0.5 points of Astra at about a fifth of the cost, and it scores 5.3 points higher than GPT-6.1 Sol on GDPval v2. It keeps GPT-6.1 Sol's prices: $2 input, $10 output and $0.10 cached input per million tokens.

Sol sits right after Claude Opus 5.5 in the Pro model list, ahead of GPT-6.1 Sol, which stays available. On Ultra, Astra takes GPT-6 Astra's place beside Claude Fable 5.2, and GPT-6 Astra stays available.

Pick them in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model gpt-6.2-sol or /model gpt-6.2-astra.

Both read images and have a 1.05M-token context window, with up to 128K output tokens. Their effort control runs low, medium, high, xhigh and max. When you pin them, they draw from your plan's manual allowance like every other named model. Astra is pinned by hand only; Roost never picks it.

November 14, 2026

Local models: run Perch on a model on your own computer

Perch can run on a model served from your own computer instead of a hosted one. Turns on a local model are not metered against your plan's allowance.

In Perch Desktop, open Settings, then Models. Perch finds Ollama and LM Studio on the computer and lists the models each one has; pick one and choose Use. A llama.cpp server, or a model app on another computer on your network, goes in by its address. In the CLI, run perch byolm.

Saving a model runs a quick connection test. It checks that the model can call tools, which Perch needs to read files and run commands, so you find out up front, not mid-task, if a model would stall on the first file read. A passing test also records how fast the model answers.

Local models are open to every plan, in Perch Desktop and the CLI. They are not in the browser, because a model on your computer can only be reached from your computer.

November 9, 2026

Claude Fable 5.2 is on Perch AI Ultra, day one

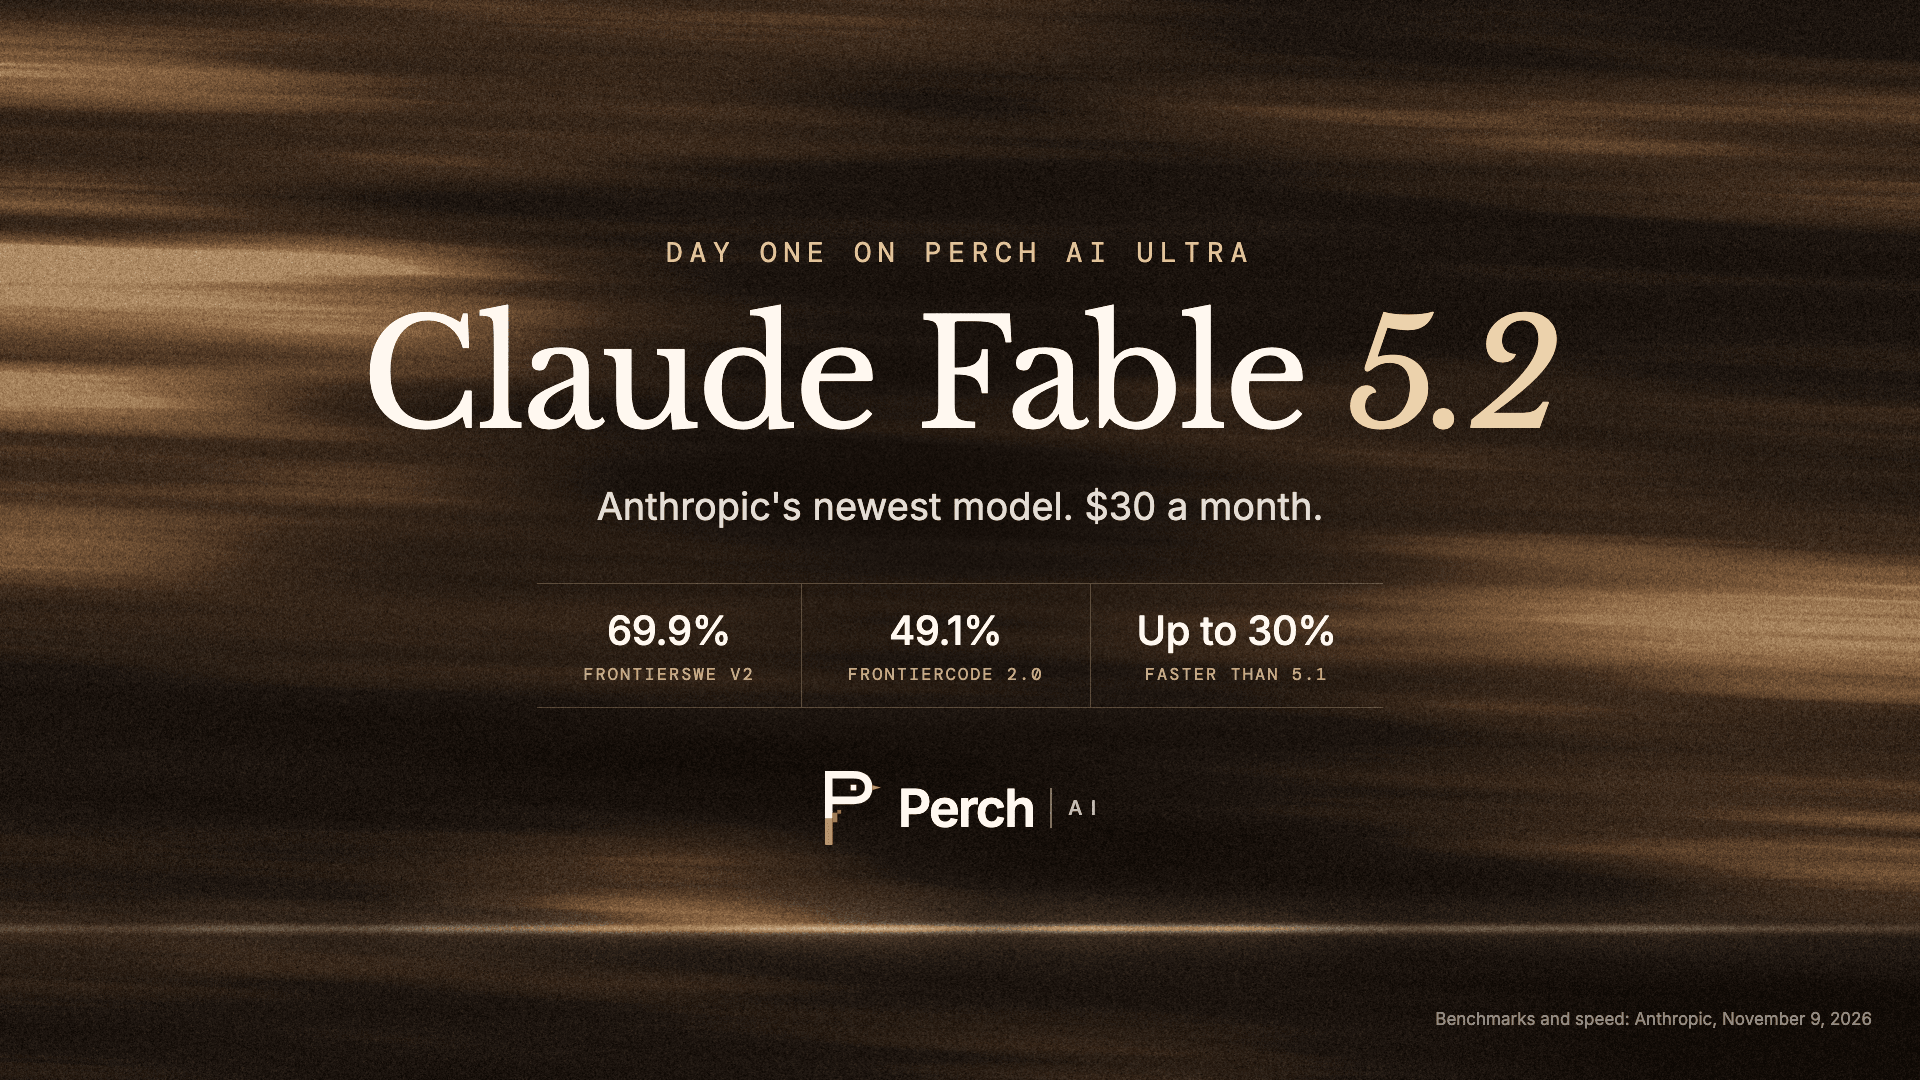
Claude Fable 5.2, day one on Perch AI Ultra. Anthropic's newest model, $30 a month. 69.9% on FrontierSWE v2, 49.1% on FrontierCode 2.0, and up to 30% faster than Fable 5.1.

Claude Fable 5.2, released today by Anthropic, is on Perch AI Ultra from day one, $30 a month. It takes Fable 5.1's place at the top of the Ultra lineup, and Fable 5.1 stays available.

In Anthropic's own testing, it scores 69.9% on FrontierSWE v2, up from 56.3% for Fable 5.1, and 49.1% on FrontierCode 2.0, ahead of Claude Opus 5.5 at 45.5%. Anthropic says it writes up to 30% faster than Fable 5.1 and blocks about 55% fewer requests.

It also costs 20% less than Fable 5.1: $8 input, $40 output and $0.20 cached input per million tokens, so Ultra's included usage goes further.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model claude-fable-5.2.

It reads images and has a 1M-token context window. Its effort control runs low, medium, high, xhigh and max. Like every Ultra-only model, you pin it yourself; Roost never picks it, and it draws from Ultra's manual allowance.

Claude Fable 5.2's host keeps prompts and replies for up to 30 days and may have people review them for safety.

November 6, 2026

Unlimited DeepSeek V4.1 Flash on Pro and Ultra, extended through Sunday

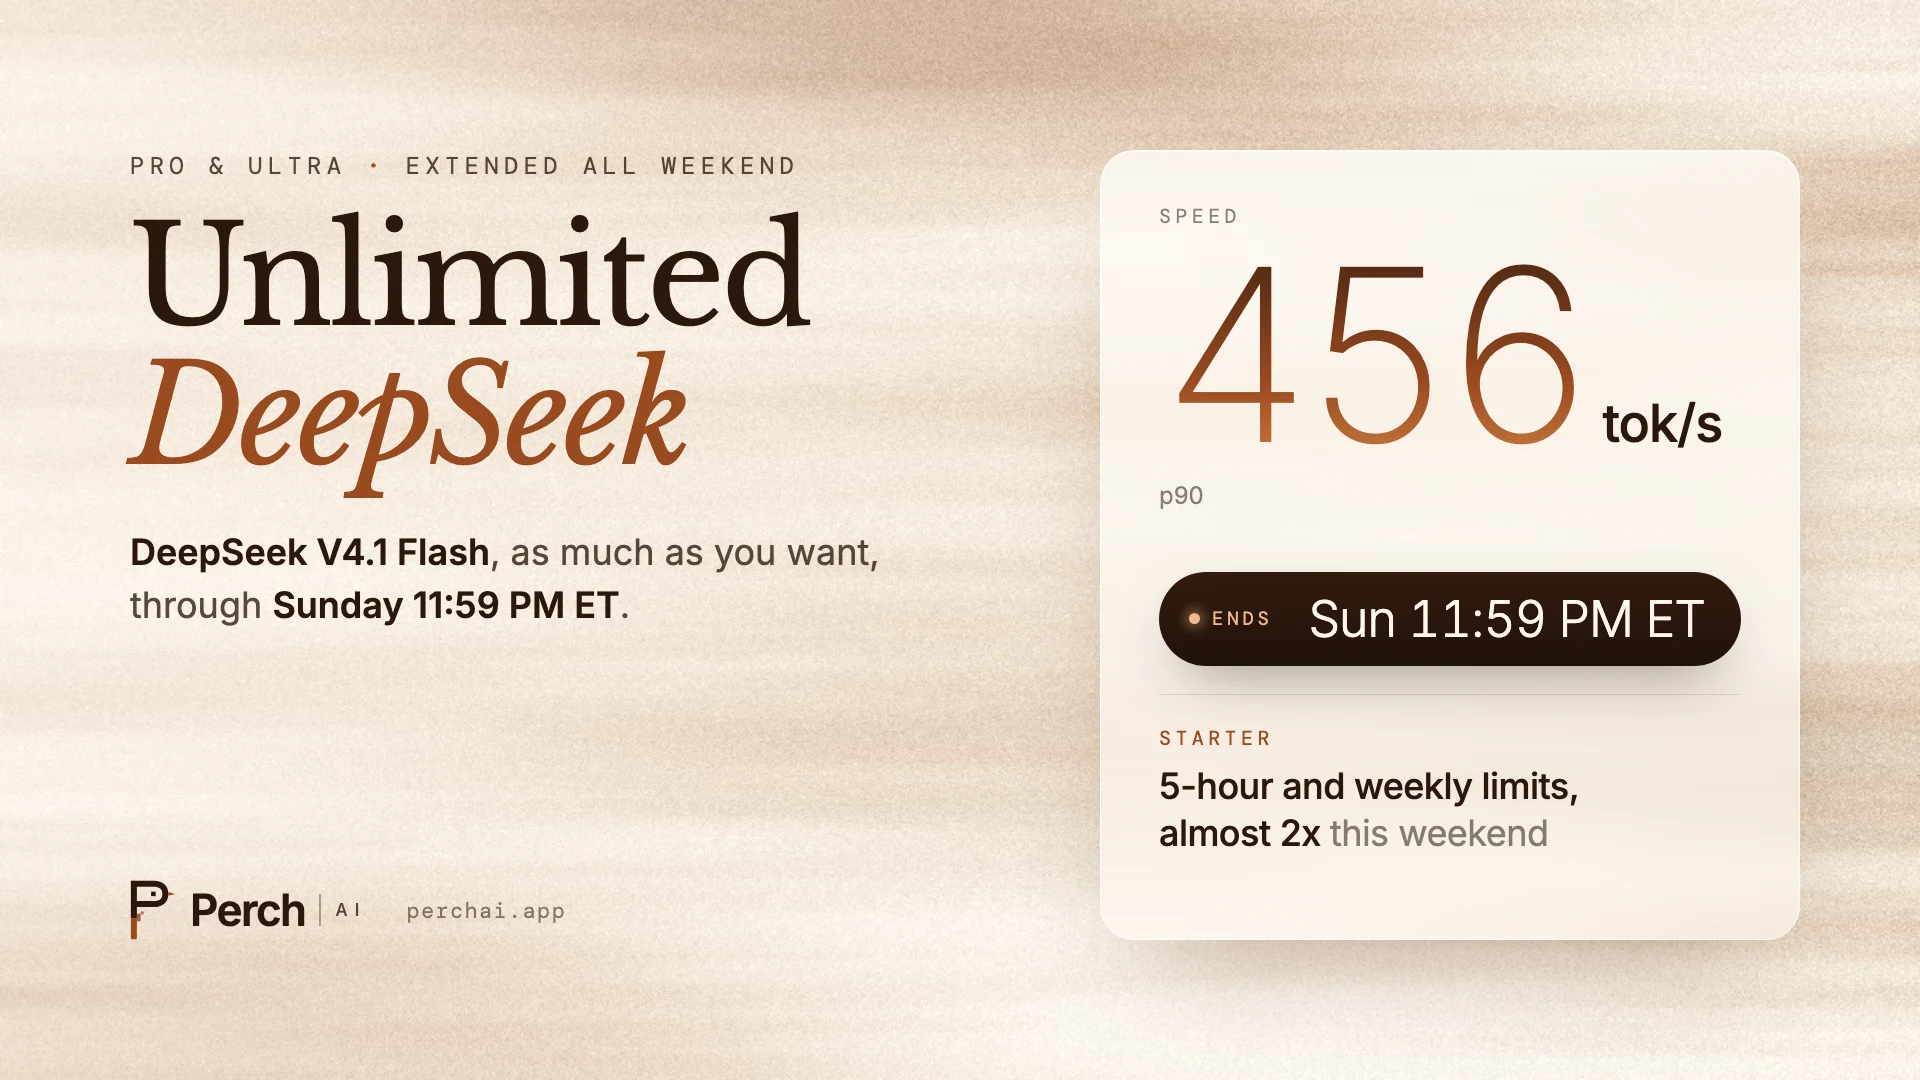
Unlimited DeepSeek, extended all weekend: DeepSeek V4.1 Flash as much as you want on Pro and Ultra through Sunday 11:59 PM ET, 456 tok/s p90, and Starter's 5-hour and weekly limits almost 2x this weekend.

We're keeping it going. DeepSeek V4.1 Flash stays unlimited on Pro and Ultra through 11:59 PM ET on Sunday, November 8. None of it counts toward your plan's allowance or its usage limits.

It's fast, too: across the first 16,400 promo replies, the p90 speed was 456 tokens per second.

Pick DeepSeek V4.1 Flash (Promo) in the model menu of the Perch desktop app. Up to 3 requests can run at once per account.

On Starter? Your 5-hour and weekly limits are almost 2x this weekend. Pro is $10 a month and Ultra $30.

November 6, 2026

DeepSeek V4.1 Flash is unlimited on Pro and Ultra for 24 hours

Unlimited DeepSeek: DeepSeek V4.1 Flash, as much as you want on Pro and Ultra for the next 24 hours. It doesn't count toward your plan.

For the next 24 hours, DeepSeek V4.1 Flash is unlimited on Pro and Ultra. Send as much as you want: none of it counts toward your plan's allowance or its usage limits.

Pick DeepSeek V4.1 Flash (Promo) in the model menu of the Perch desktop app. Up to 3 requests can run at once per account.

The window ends at 1 AM ET on Saturday, November 7. After that, the promo model leaves the menu. The regular DeepSeek V4.1 Flash 1017 stays and uses your plan's allowance as usual. On Starter? Pro is $10 a month and Ultra $30.

November 5, 2026

CLI agents: Claude Code and Codex, right inside Perch

Pick Claude Code or Codex in the model picker, under On this computer, and it works inside Perch on your own Claude Code or Codex plan. Each one works in its own copy of your repo, so you can run several at once, each in its own chat.

When one is done, bring its work back from the chat: merge its changes into your branch as one commit, commit them on the agent's own branch, or open a pull request.

CLI agents are in the Perch desktop app, version 2.5.4 or newer, on macOS, Windows and Linux, for Pro and Ultra.

November 3, 2026

Crouton Alpha, a new stealth model, is free on every Perch AI plan

Crouton Alpha, a new stealth model. Free on every Perch AI plan, for a limited time.

Crouton Alpha, a new stealth model, is now on Perch. It is free on every plan, Starter included, for a limited time.

Its maker has not been named yet. It is a lightweight model built for coding, agent work and multimodal tasks, and it is meant for high-volume, repeated work: agent sub-tasks, tool use and reading through documents.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model crouton-alpha.

It reads images and has a 1M-token context window. It always thinks, so its effort runs low through max.

As with any stealth preview, its maker may keep prompts and responses, though not to train on them. For sensitive work, pick another model.

Free on every plan for a limited time

Crouton Alpha is free on Starter, Pro and Ultra from November 3, 2026, while its preview stays free. When the free preview ends, it leaves the lineup.

  • Starter, Pro and Ultra

    Crouton Alpha

    /model crouton-alpha

On Starter, its usage counts toward the included allowance, like every Starter model. On Pro and Ultra, it does not use the manual-model allowance and counts toward Roost's fair-use limits instead. No paid plan or credit card is required.

November 1, 2026

Speak your language: Perch in eight languages, dictation in 63

Perch's own screens now come in eight languages: English, Español, 简体中文, 繁體中文, 日本語, Tiếng Việt, Bahasa Indonesia and ไทย. Choose one in Settings, under General. The choice is saved to your account, so it follows you to the desktop app, the web and your phone. Perch answers in whatever language you write in, with nothing to set.

Voice dictation understands 63 languages and works out which one you are speaking on its own. Press the mic, speak, and your words land in the message box for you to check before you send.

Dictation is in beta on Starter, Pro and Ultra, in Perch AI on the web, Perch Terminal on the web and the Perch desktop app. During the beta it does not use your plan's usage.

October 31, 2026

The agent browser, rebuilt in Perch 2.5

The agent browser is a real browser inside the Perch desktop app, in a panel beside the chat, and Perch drives it the way you would. In Perch 2.5 it checks your site at any size, and every chat gets its own tab.

Ask Perch to check a page at phone size and fix what breaks. It opens your dev server in the panel, switches between desktop, tablet and phone sizes, reads the console and failed requests, makes the edit, reloads and looks again. Because each chat drives its own tab, two chats, or a chat and its sub-agents, can browse at the same time.

It also works behind your own sign-ins. Perch uses the sessions you are already signed into, and when it reaches a login it brings the panel forward so you sign in yourself. You never hand it a password.

October 30, 2026

November bonus: extra DeepSeek V4.1 Flash 1017 on Pro and Ultra

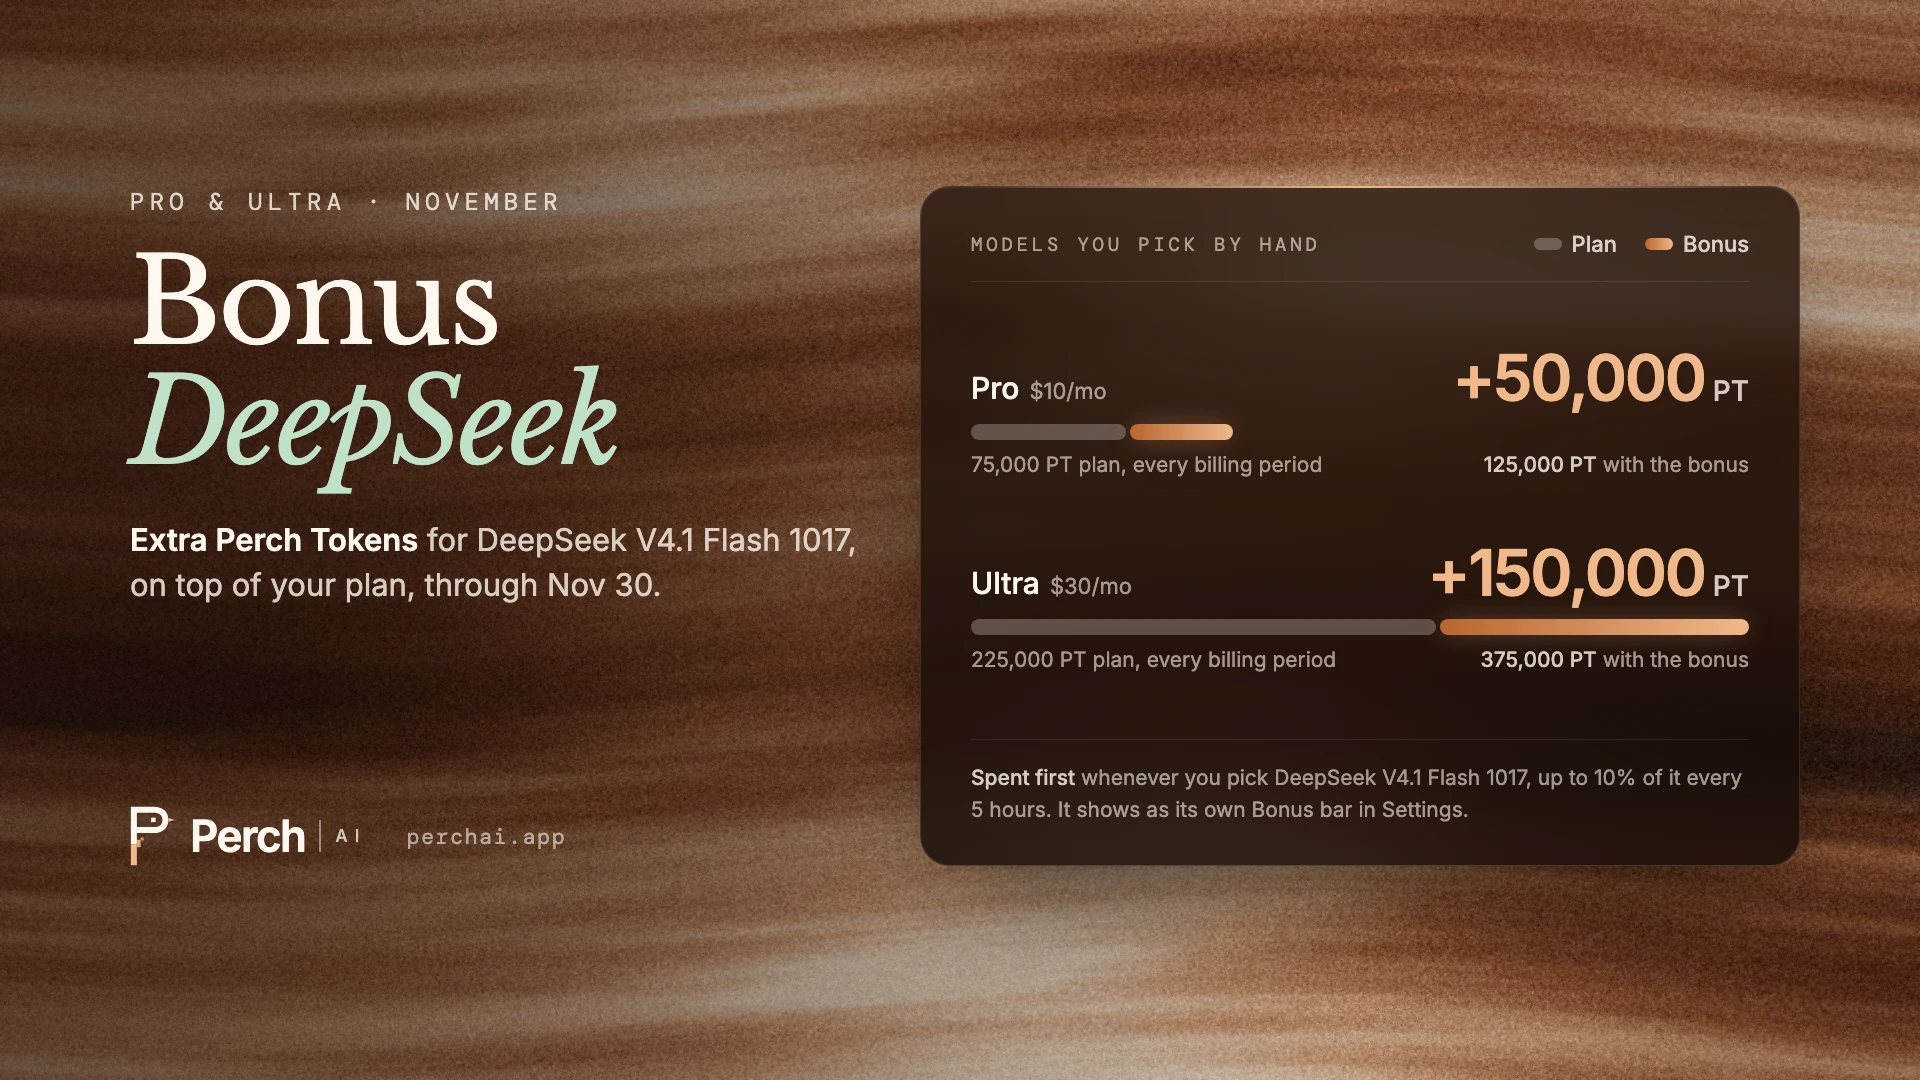
Bonus DeepSeek: Pro gets +50,000 PT and Ultra +150,000 PT for DeepSeek V4.1 Flash 1017, on top of the plan, through November 30.

Through November 30, Pro and Ultra get a bonus of Perch Tokens for DeepSeek V4.1 Flash 1017, on top of the plan's own allowance: 50,000 PT on Pro and 150,000 PT on Ultra.

The bonus is spent first whenever you pick DeepSeek V4.1 Flash 1017 yourself: in Perch AI on the web at chat.perchai.app, in the Perch desktop app, or in the CLI with /model deepseek-v4.1-flash-1017. Up to 10% of it can be used in any 5 hours. Past that, the call simply uses your plan's normal allowance.

It shows as its own Bonus bar in Settings, with what is left and when it ends. Bonus spend does not count against your plan's own limits, and the automatic modes keep their own allowance as before.

When the bonus is used up, or after November 30, DeepSeek V4.1 Flash 1017 goes back to your plan's allowance as usual. On Starter? Pro is $10 a month and Ultra $30.

Update, November 19: the bonus is now 75,000 PT on Pro and 225,000 PT on Ultra, twice the DeepSeek room, and a fresh bonus of the same size runs through December 31.

October 28, 2026

Sub-sessions: chats that run beside yours

Some parts of a job are too big to hand to a helper and forget. For those, Perch can start a sub-session: a full chat of its own that runs beside the one you are in and reports back to it.

Perch asks first. It shows a card with the title, why it suggests one, the folder it runs in and the model, and starts when you click Start. Each sub-session sits in the chat list under the chat that started it, so you can keep working, open it, steer it with a message, or keep talking to it later.

Sub-sessions are on every plan, in the Perch Terminal app and the interactive CLI. A sub-session's turns count like any message you send.

October 26, 2026

GPT-6.1 Terra is on Perch AI Pro, day one

GPT-6.1 Terra, day one on Perch AI Pro. OpenAI's newest model, $10 a month.

GPT-6.1 Terra, released today by OpenAI, is on Perch AI Pro from day one, $10 a month. It sits right after GPT-6.1 Sol in the Pro model list.

Terra is the fast, efficient model in OpenAI's GPT-6.1 family, built for visual reasoning, computer use and clear writing. In OpenAI's own testing it solves 50.3% of Terminal-Bench 4.0 tasks at max effort, more than double GPT-5.6 Terra's 21.5%. On OpenAI's internal set of error-inducing prompts, its error rate at low effort falls to 16.7%, from 53.6% for GPT-5.6 Terra. OpenAI says it completes agent tasks more than three times faster than GPT-6.1 Sol.

It also costs half as much as GPT-6.1 Sol: $1 input, $5 output and $0.05 cached input per million tokens, so Pro's included usage goes further. For the most complex coding tasks, OpenAI says GPT-6.1 Sol remains the better choice, and it stays on Pro.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model gpt-6.1-terra.

It reads images and has a 1.05M-token context window. Its effort control runs off, low, medium, high, xhigh and max.

It is a separate pick from GPT-5.6 Terra, which stays on Pro. It is not one of the automatic modes: you choose it from the model list. It uses Pro's included premium-model usage and is not available on Starter.

October 26, 2026

Subagents: one job, split across agents

Perch can hand parts of a job to agents of their own. Each one gets a narrow task and its own context, does the work, and returns only its findings, so the main thread stays clear enough to reason about what came back. Independent pieces run at the same time.

Two agents are always there: general, which searches, reads, edits files and runs commands, and explore, which only reads and reports back with file and line references. Each agent's run is saved as a chat of its own under the chat that started it, so you can open it and see what it did. Add your own with a Markdown file in .perch/agents/.

Subagents work in the Perch desktop app.

October 25, 2026

Qwen 3.8 Max is free on Starter until November 20

Qwen 3.8 Max, now on Perch AI Starter. Free until November 20. No credit card needed.

Qwen 3.8 Max, the top model in Alibaba's Qwen 3.8 family, is now free on the Perch AI Starter plan. The offer runs until November 20, 2026, at noon Eastern.

Pick Qwen 3.8 Max in the model picker in the Perch desktop app. In the terminal, run /model qwen-3.8-max.

It reads images and has a 262K-token context window. Its effort control runs off, low, medium and high.

Starter is free, and no credit card is required. Qwen 3.8 Max's usage counts toward Starter's included allowance, like every Starter model. On Pro, it stays a regular pinned model.

Free on Starter until November 20

Qwen 3.8 Max is on the free Starter plan from October 25, 2026, at 4 p.m. Eastern until November 20, 2026, at noon Eastern. When the offer ends, it leaves the Starter lineup.

  • Starter, until November 20

    Qwen 3.8 Max

    /model qwen-3.8-max

Starter is free, with usage counting toward its included allowance, like every Starter model. No paid plan or credit card is required.

October 23, 2026

Kimi K3.1 Pro is on Perch AI Pro, day one

Kimi K3.1 Pro, day one on Perch AI Pro. Moonshot's newest model, $10 a month.

Kimi K3.1 Pro, released today by Moonshot AI, is on Perch AI Pro from day one, $10 a month. It sits right after GPT-6.1 Sol in the Pro model list.

It is the first model in Moonshot's K3.1 series. In Moonshot's own testing it scores 65.7% on Terminal-Bench 4.0 and 64.4 on OfficeQA Pro v2. On Moonshot's hardest internal hallucination test, run with tools, its claim-level error rate falls to 8.3%, from 23.4% for Kimi K3.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model kimi-3.1-pro.

It reads images and has a 1M-token context window. Its effort control runs off, low, high and max.

It is a separate pick from Kimi K3, which stays on Pro. It is not one of the automatic modes: you choose it from the model list. It uses Pro's included premium-model usage and is not available on Starter.

October 22, 2026

Steer and queue: talk to Perch while it works

You do not have to wait for Perch to finish before you say something. While a task runs, the message box stays open.

Press Enter and your message joins the running task. Perch reads it at its next step instead of starting over, and a note under your message says when. Press Tab and the message waits its turn, then runs the moment the task ends. Esc stops the task.

Steer and queue work in Perch Terminal on the web, in the desktop app and in the CLI, and the same way when the task runs in the cloud or on your other computer.

October 21, 2026

Routines: set it once, it runs on its own

A routine is a task you write once and Perch runs for you: on a schedule, such as every weekday at 8:00, or when your own code calls it. Each run happens in a private cloud workspace, so your computer can be off.

Every run opens as a chat you can read and continue, and Perch can tell you by email or phone notification what it did. Routines suit work you would otherwise ask for again and again: a morning review of a repository, a weekday pass over a support inbox, a weekly summary.

Routines are in beta on Pro and Ultra. Open Routines in the Perch Terminal sidebar, on the web or in the desktop app, and choose New routine.

October 19, 2026

MiniMax M3.1 Flash is free on Starter

MiniMax M3.1 Flash, free on Perch AI Starter for a limited time. MiniMax's new agentic model, 73.7% on DeepSWE v1.1 in MiniMax's testing.

MiniMax M3.1 Flash, released today, is on Perch from day one. It is free on the Starter plan for a limited time.

MiniMax built M3.1 Flash for agent work, coding, computer use and security tasks. In MiniMax's own testing it scores 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2 and 82% on CyberGym.

If you tried Space Bunny Alpha on Starter in September, you have met it before. MiniMax confirmed that Space Bunny, the anonymous model, was an early version of M3.1 Flash.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model minimax-m3.1-flash-starter.

It reads images and has a 1M-token context window. It always thinks, so its effort runs low through max.

Update, October 25: the offer has ended, and MiniMax M3.1 Flash has left the Starter lineup.

Free on Starter for a limited time

MiniMax M3.1 Flash was on the free Starter plan from October 19 to October 25, 2026. The offer has ended, and the model has left the Starter lineup.

  • Starter, for a limited time

    MiniMax M3.1 Flash (Starter)

    /model minimax-m3.1-flash-starter

Starter is free, with usage counting toward its included allowance, like every Starter model. No paid plan or credit card is required.

October 17, 2026

DeepSeek V4.1 Flash 1017 is on Perch AI Pro, day one

DeepSeek V4.1 Flash 1017, day one on Perch AI Pro, $10 a month. DeepSeek's October 17 update, 77.0 on DeepSWE v1.1 in DeepSeek's testing.

DeepSeek V4.1 Flash 1017, DeepSeek's October 17 update to V4.1 Flash, is on Perch AI Pro from day one, $10 a month. It sits right after GPT-6.1 Sol in the Pro model list.

DeepSeek reports substantial improvements across benchmarks over the earlier V4.1 Flash. In its own testing the update scores 77.0 on DeepSWE v1.1 and 42.3 on Terminal-Bench 4.0.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model deepseek-v4.1-flash-1017.

It reads images, and its 1M-token context is shared between what you send and what it writes. Its effort control runs off, low, high and max.

It is a separate pick from DeepSeek V4.1 Flash, which stays on Starter and Pro. It is not one of the automatic modes: you choose it from the model list. It uses Pro's included premium-model usage and is not available on Starter.

October 16, 2026

Beam 1.0 is free on Starter for a week

Beam 1.0, free on Perch AI Starter until October 23 and also on Pro. Reflection's open-weight model for coding and agentic work.

Beam 1.0, Reflection's first open-weight model, is on Perch from day one. It is free on the Starter plan for one week, and it joins the Pro lineup to stay.

Reflection built Beam for coding, reasoning and long-running agent work. It is a 501B-parameter mixture-of-experts model with 23B active, released on October 16 under the Apache 2.0 license. In Reflection's own testing it scores 80.9 on SWE-bench Verified and 80.1 on Terminal-Bench 2.1.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run the command for your plan below.

Beam has a 1M-token context window and always thinks. It reads text only, so screenshots and scans you share go through Perch's image-reading step first.

Free on Starter for a week

Beam 1.0 is on the free Starter plan until Thursday, October 23, 2026, at 2 p.m. Eastern. On Pro it stays after that.

  • Starter, until October 23

    Beam 1.0 (Starter)

    /model beam-1.0-starter
  • Pro

    Beam 1.0

    /model beam-1.0

Starter is free, with usage counting toward its included allowance, and Starter runs Beam at low effort. On Pro, Beam 1.0 is a regular pinned model: it uses the manual-model allowance and runs the full effort range, low through max.

October 13, 2026

Gemini 4 Argon is on Perch AI Pro, day one

Gemini 4 Argon, day one on Perch AI Pro, $10 a month. Number one on the Vals Index and on Vals Finance Agent.

Gemini 4 Argon, Google's newest frontier model, is on Perch AI Pro from day one, $10 a month. It sits at the top of the Pro model list.

Google built Argon for long, real-world work in coding, finance and legal. On Vals.ai's independent benchmarks it ranks first on the Vals Index, which scores finance, legal, coding and tax tasks, and first on Finance Agent.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model gemini-4-argon.

Argon reads images, so you can hand it screenshots, scans and photos. Its 1M-token context is shared between what you send and what it writes.

It is not one of the automatic modes: you choose it from the model list. It uses Pro's included premium-model usage and is not available on Starter.

October 12, 2026

Claude Opus 5.5 is now on Perch AI Pro

End card from the Claude Opus 5.5 launch film: the Perch AI wordmark over the words Claude Opus 5.5, now live on Perch AI Pro, $10 a month.

Claude Opus 5.5 from Anthropic is now on Perch AI Pro, $10 a month. It sits at the top of the Pro model list.

Pick it in Perch AI on the web at chat.perchai.app or in the Perch desktop app. In the terminal, update the CLI and run /model claude-opus-5.5.

Opus 5.5 reads images, so you can hand it screenshots, scans and photos.

It is not one of the automatic modes: you choose it from the model list. It uses Pro's included premium-model usage and is not available on Starter.

October 10, 2026

Artifacts: make it, change it, share it

Ask Perch for a memo, an interactive calculator, a dashboard or a table, and it makes an artifact: a piece of work you open in a panel beside the chat instead of reading it in the conversation.

Ask for a change in the same chat and Perch saves a new version. Step between versions and see what changed. To share one, create a link: anyone with it can view, copy or download that version without signing in, and cannot see your chat or your other versions.

Everything Perch makes collects in the Artifacts library in the sidebar, across your chats and workspaces. Artifacts are on every plan. In the Perch desktop app, the CLI and Cloud Agents, Perch makes documents, interactive pages, code and tables as it works; Perch AI on the web makes documents you can download.

October 6, 2026

Cloud Agents now live in Perch AI

Hand Perch the job. Pick it up from anywhere. Cloud Agents run in a private cloud workspace and keep working after you close the laptop. Start a task from your browser or phone, follow its progress, and review the result when you return.

Need the files and tools on your own computer? Turn on Remote Control in Perch Desktop and send tasks from anywhere. They run on your computer while it stays awake with Perch open.

Cloud Agents and Remote Control are in beta for Pro, with availability enabled account by account.

Free Launch Celebration Promo

Celebrate the launch with GPT-6.1 Sol, Qwen 3.8 Max 0902, and Qwen 3.8 Flash. The offer runs through October 13, 2026, at 2:30 p.m. Eastern.

  • Pro only

    GPT-6.1 Sol

    /model gpt-6.1-sol
  • Starter + Pro

    Qwen 3.8 Max 0902

    /model qwen-3.8-max
  • Starter + Pro

    Qwen 3.8 Flash

    /model qwen-3.8-flash

Starter is free, with usage counting toward its included allowance. On Pro, these promotional selections do not use your manual-model allowance; they count toward Roost’s fair-use limits at half price. The usual five-hour and weekly limits apply.

September 29, 2026

GPT-6.1 Sol is already in Perch

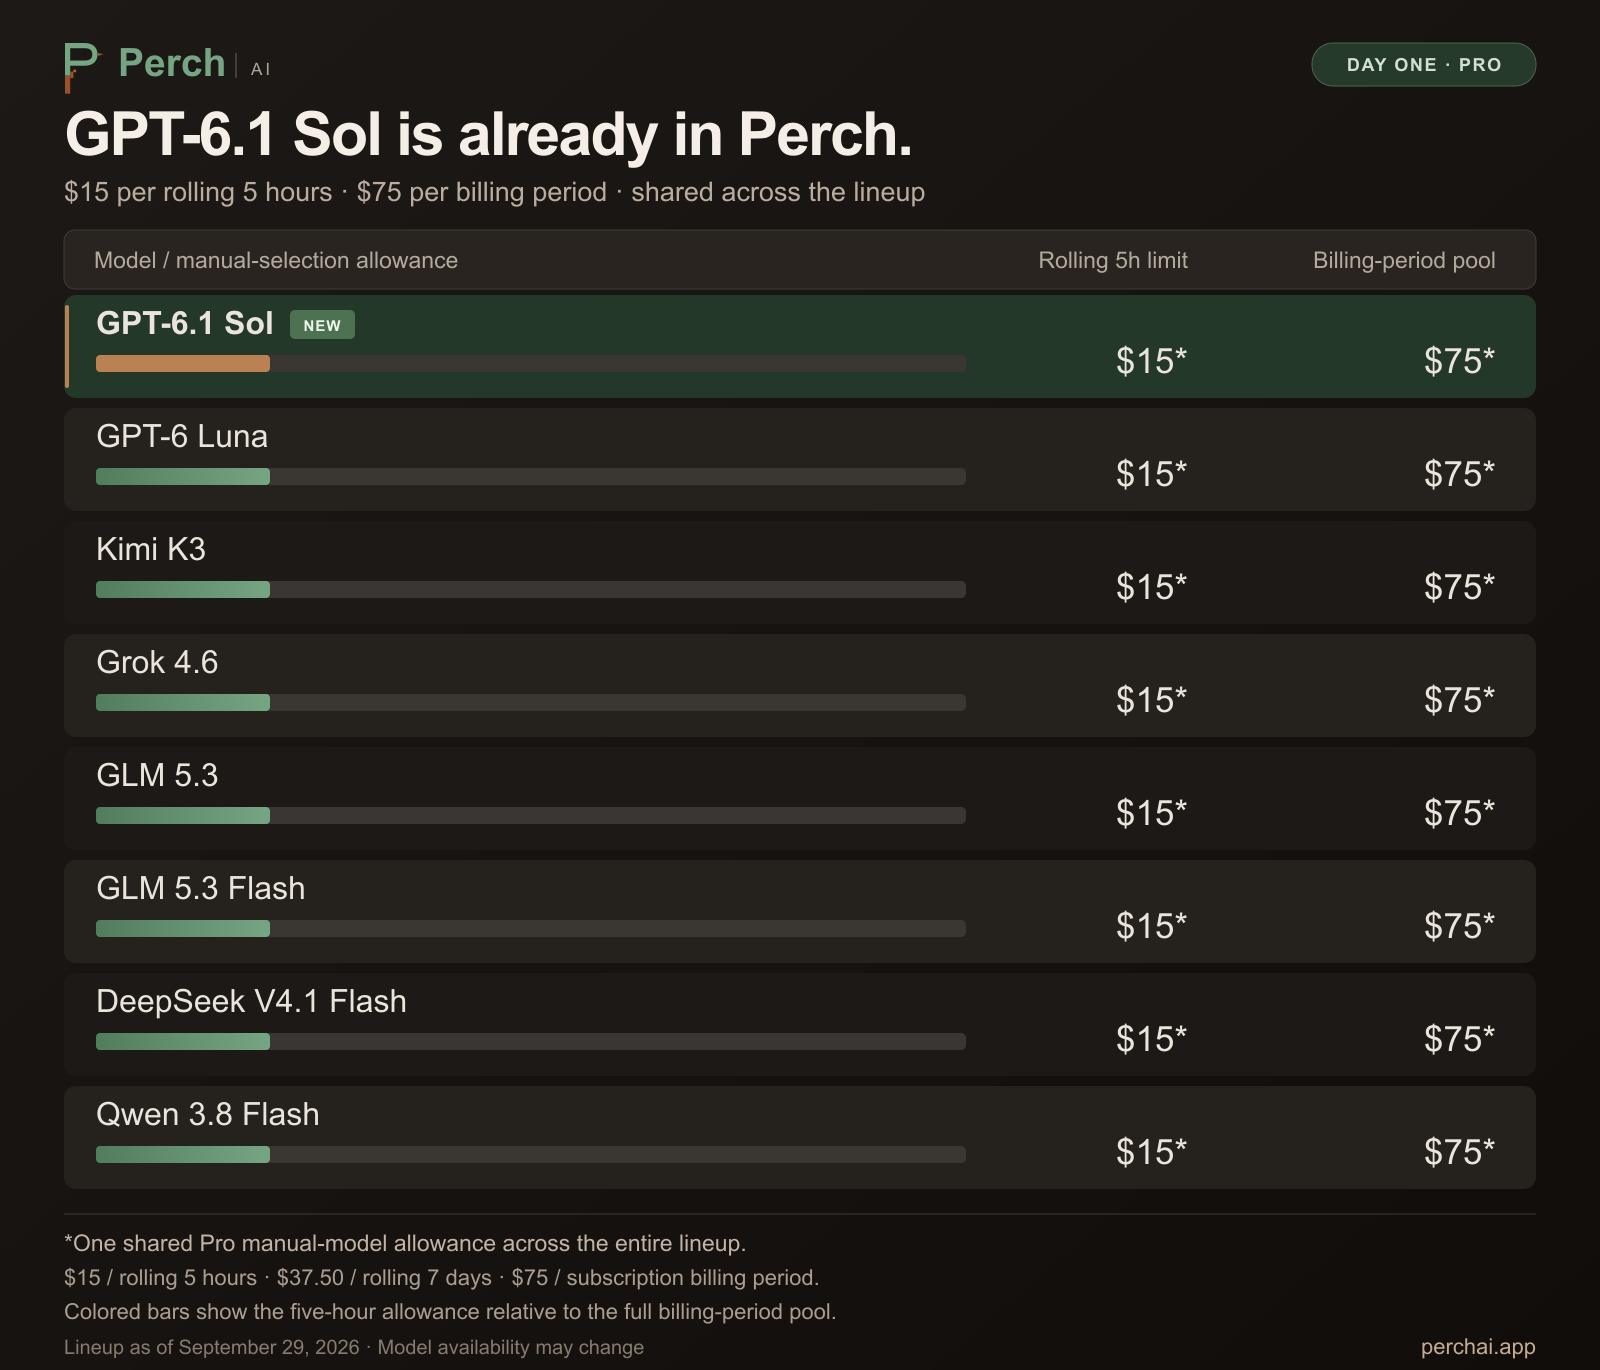
GPT-6.1 Sol joins Perch Pro on day one. The featured lineup runs through Qwen 3.8 Flash; all models share a $15 rolling five-hour limit and $75 billing-period manual-model allowance.

OpenAI's newest Sol model is now available on Perch Pro, from day one. It brings stronger coding, complex document understanding, and multi-step agent work to your existing workspace.

In OpenAI's evaluations, GPT-6.1 Sol approaches Astra's performance across several demanding tasks while keeping GPT-6 Sol's base input and output prices. Cached input is now half the price.

Select it in Perch Web, Desktop, or CLI with /model gpt-6.1-sol. It joins the full Pro lineup and uses your existing shared model-selection allowance.

New model. Same Perch. Ready when you are.

September 26, 2026

Kimi K3 is free on Starter for a limited time

Kimi K3 is now available on Perch's free Starter plan for a limited time. Pin it in Perch Desktop or the CLI with /model kimi-k3-starter.

Space Bunny Alpha and DeepSeek V4.1 Flash are also available on the free Starter plan. Pin them with /model space-bunny-alpha and /model deepseek-flash-starter.

No paid plan or credit card is required.

September 22, 2026

A copper sunrise and ivory crescent moon above a dark Perch-inspired landscape.
PerchAI

OPENAI GPT-6 · DAY ONE IN PERCH

GPT-6 Sol and Luna are live in Perch on day one

Go deep with Sol. Move fast with Luna. Both are ready in Perch today.

Explore the models

GPT-6 Sol

Pro

For complex coding and agentic workflows.

GPT-6 Luna

Pro

For focused, high-volume work.

GPT-6 Sol and GPT-6 Luna are available in Perch on launch day, both on Pro. Sol is built for complex coding and agentic workflows; Luna is OpenAI's most efficient GPT-6 model for focused work you need to do at scale. Choose either in Perch AI Web, Desktop, or the CLI with /model gpt-6-sol or /model gpt-6-luna.

Both models have a 1.05M-token context window, image input, streaming, tool calls, structured output, and adjustable reasoning. Published base rates are $2 input / $10 output per million tokens for Sol, and $0.10 input / $0.50 output for Luna; cached input is $0.20 and $0.01 respectively. OpenAI applies higher rates to prompts above 272K input tokens. Full lineup and rates: https://perchai.app/docs/concepts/models.

September 19, 2026

DeepSeek V4.1 Flash is live in Perch

DeepSeek V4.1 Flash is now available in Perch as a Pro model. Pin it in Perch Desktop, the web app, or the CLI with /model deepseek-v4.1-flash. DeepSeek V4 Flash 0731 (Starter) is also available free to Starter users; pin it with /model deepseek-v4-flash-0731-starter.

Update, September 22: DeepSeek V4.1 Flash is now also available on Starter. The Starter pool rotates, subject to availability.

V4.1 Flash has a 1M-token context window, native multimodal input, tool use, and graded reasoning you can set to Low, High, or Max. It is built for long-context research, coding, and multi-step agent work.

Published rates are $0.30 / $1.20 per million tokens (input / output), with cached input at $0.03. Full model list and rates: https://perchai.app/docs/concepts/models.

September 16, 2026

Three powerful models are now free on Starter

GLM 5.3 Flash, GPT-5.6 Luna, and the brand-new stealth model Union Alpha are now available on Perch's free Starter plan. No paid plan or credit card is required. Let Roost choose for you, or pin one in Perch Desktop, the web app, or the CLI with /model glm-5.3-flash-starter, /model gpt-5.6-luna, or /model union-alpha.

GLM 5.3 Flash brings a 1M-token context window, native image input, tool use, and graded reasoning for fast coding and long-context work. GPT-5.6 Luna pairs a 1.05M-token context window with native vision, tool use, and adjustable reasoning. Union Alpha is a brand-new stealth preview with a 262K-token context window, multimodal input, and tool use.

All three are included in Starter's 20,000 PT monthly hosted-usage allowance. Usage counts against that allowance, and the rotating Starter lineup may change as provider arrangements change.

September 14, 2026

The GPT-5.6 family has landed in Perch

The GPT-5.6 family in Perch: Sol and Terra on Pro, and Luna on Starter and Pro.

GPT-5.6 Sol, Terra, and Luna are now available in Perch. Sol and Terra are available on Pro, while Luna is available on every plan, including Starter. Pin them in Perch Desktop, the web app, or the CLI with /model gpt-5.6-sol, /model gpt-5.6-terra, or /model gpt-5.6-luna.

Choose Sol for the most demanding professional work, Terra for a balance of intelligence and cost, or Luna for fast, efficient, high-volume tasks. All three have a 1.05M-token context window, native image input, streaming, tool calls, structured output, and adjustable reasoning.

Published rates are $4.00 / $20.00 per million tokens (input / output) for Sol, $2.00 / $12.00 for Terra, and $0.20 / $1.20 for Luna. Cached input is $0.40, $0.20, and $0.02 respectively. Full model list and rates: https://perchai.app/docs/concepts/models.

September 10, 2026

GLM 5.3 and Kimi K3 are live in Perch

GLM 5.3 and Kimi K3 are now available in Perch as Pro models, joining the premium lineup at the top of the list. Both have a 1M-token context window, streaming, tool calls, and graded reasoning you can set to Low, High, or Max. Pin either by hand in Perch Desktop, the web app, or the CLI with /model glm-5.3 or /model kimi-3.

GLM 5.3 is Zhipu's newest GLM, built for strong reasoning and agentic coding across long context. Kimi K3 is Moonshot's newest and largest Kimi, with native image input, and it sits at the top of the lineup for the hardest multi-step work.

Published rates are $1.75 / $5.50 per million tokens (input / output) for GLM 5.3, with cached input at $0.325, and $3.30 / $16.50 for Kimi K3, with cached input at $0.33. Full model list and rates: https://perchai.app/docs/concepts/models.

September 5, 2026

GLM 5.3 Flash is live in Perch

GLM 5.3 Flash is now available in Perch as a Pro model, joining the premium lineup alongside GLM 5.2. It has a 1M-token context window, native image input, streaming, tool calls, and graded reasoning you can set to Low, High, or Max. It is built for fast, low-cost work: quick coding turns, long-context reads, and high-volume agent runs. Pin it by hand in Perch Desktop, the web app, or the CLI with /model glm-5.3-flash.

Published rates are $0.15 / $0.50 per million tokens (input / output), with cached input at $0.05, among the cheapest in the premium lineup. Full model list and rates: https://perchai.app/docs/concepts/models.

August 29, 2026

Grok 4.6 is live in Perch

Grok 4.6 is now available in Perch as a Pro model, replacing Grok 4.3 in the premium lineup. It brings a 500K-token context window, native image input, streaming, structured output, and adjustable reasoning that can be switched off or set from Low through XHigh. Pin it by hand in Perch Desktop, the web app, or the CLI with /model grok-4.6.

Published rates are $2.20 / $6.60 per million tokens (input / output), with cached input at $0.55. Full model list and rates: https://perchai.app/docs/concepts/models.

August 27, 2026

Qwen 3.8 Flash is live in Perch

Qwen 3.8 Flash is now available in Perch — the newest Qwen Flash model, with a 1M-token context window. It is a Pro model built for fast, low-cost work: quick coding turns, long-context reads, and high-volume agent runs where you want speed without spending much. Pin it by hand in Perch Desktop, the web app, or the CLI with /model qwen-3.8-flash.

Published rates are $0.16 / $0.47 per million tokens (input / output), with cached input at $0.016 — among the cheapest in the lineup. Full model list and rates: https://perchai.app/docs/concepts/models.

August 24, 2026

MiniMax M3 is free in Perch

MiniMax M3 is a 1M-context model, and for a limited time it is free to run on every plan, Starter included. Pinning it does not draw down your monthly usage, so you can lean on it for long-context and coding work and keep your allowance for everything else. Normal fair use still applies.

Pin it in Perch Desktop, the web app, or the CLI with /model minimax-m3-free. With a 1M-token context window, it is a strong fit for large codebases, long document review, and multi-step agent runs. Want maximum reliability? Pro users can switch to the standard MiniMax M3 at any time with /model minimax-m3.

This is a limited-time offer. When it ends, the free MiniMax M3 leaves the free lineup; the standard MiniMax M3 stays available on Pro. Full model list and rates: https://perchai.app/docs/concepts/models.

August 22, 2026

Ox Alpha is free in Perch

Ox Alpha is a new 1M-context model, and for a limited time it is free to run on every plan, Starter included. Pinning it does not draw down your monthly usage, so you can lean on it for long-context and coding work and keep your allowance for everything else. Normal fair use still applies.

Pin it in Perch Desktop, the web app, or the CLI with /model ox-alpha. With a 1M-token context window and multimodal input, it is a strong fit for large codebases, long document review, and multi-step agent runs.

This is a limited-time offer. When it ends, Ox Alpha leaves the free lineup. Full model list and rates: https://perchai.app/docs/concepts/models.

August 12, 2026

Kimi K2.7 Code is free this week

Through Wednesday, August 19, pinning Kimi K2.7 Code is free on Pro. Runs on it do not draw down your monthly usage, so you can make it your default for the week and keep your allowance for everything else. Normal fair use still applies.

Pin it in Perch Desktop or the CLI with /model kimi-2.7. Kimi K2.7 Code is a premium Pro model with a 256K context window, native vision, and strong agentic coding, which makes it a good fit for multi-file code work, long document review, and agent runs that go many steps.

After August 19, Kimi K2.7 Code goes back to metering at $0.75 input and $3.75 output per million tokens, with cached input at $0.15. Those promo rates hold through September 1. Full lineup and rates: https://perchai.app/docs/concepts/models.

July 30, 2026

GLM 5.2 is free this week

Through Wednesday, August 5, pinning GLM 5.2 is free on Pro. Runs on it do not draw down your monthly usage, so you can make it your default for the week and keep your allowance for everything else. Normal fair use still applies.

Pin it in Perch Desktop or the CLI with /model glm-5.2. GLM 5.2 is a premium Pro model with a 200K context window and strong tool use, which makes it a good fit for long document review, multi-file code work, and agent runs that go many steps.

After August 5, GLM 5.2 goes back to metering at $1.00 input and $3.50 output per million tokens, with cached input at $0.19. Those promo rates hold through September 1. Full lineup and rates: https://perchai.app/docs/concepts/models.

July 26, 2026

Gemini 3.6 Flash is live in Perch

Gemini 3.6 Flash is now available in Perch — Google's newest Flash model, day one. Let Roost route to it automatically on Pro, or pin it by hand in Perch Desktop and the CLI with /model gemini-3.6-flash.

Published rates are $1.50 / $7.50 per million tokens (input / output). Gemini 3.5 Flash stays in the lineup. Full model list: https://perchai.app/docs/concepts/models.

July 3, 2026

Perch is live on Product Hunt today

We launched Perch on Product Hunt today. If Perch has been useful to you, come say hello. We're reading and replying to every comment.

Take a look and tell us what you think: https://www.producthunt.com/products/perch-ai. Thanks for being here early.

June 30, 2026

Gemini 3.5 Flash is live, plus usage tracking fixes

Gemini 3.5 Flash is now available in Perch. It's a fast Google model that's well suited to quick tasks and high-volume work. Let Roost route to it automatically, or hand-pick it in Perch Desktop and the CLI.

We also fixed usage reporting. The /usage command now shows your correct plan and Perch Token balance in the terminal, and Pro accounts see their full allowance. If anything still looks off, reach out at support@perchai.app.

June 28, 2026

Perch moved to faster, more reliable infrastructure

We migrated Perch to new infrastructure built for our streaming, agentic workloads.

The result: faster responses, steadier long-running sessions, and headroom to grow. Thanks for being here early.